Fugo Media
The practical problem for a new media site: where does the content come from
The practical problem is where content comes from
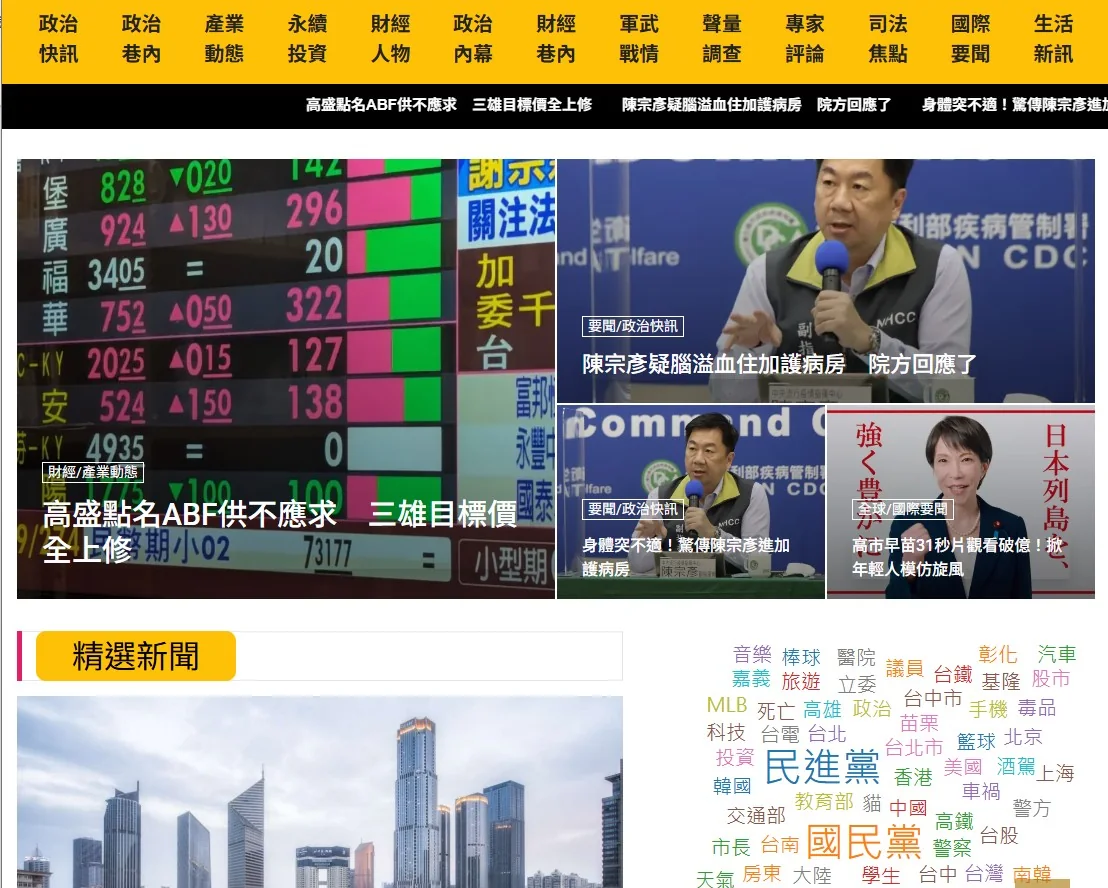
However good the layout, a media site with no content is empty. So this one has three sources: the editors, reader contributions and tip-offs (the client asked for those), and a crawler pulling articles in from news sites.
The crawler sits on a shell driven by a config file
The scheduler itself is small: it reads a file saying what to run, how often, and when it last ran. Adding a job means adding a line — the site's word cloud runs on the same shell.
It later went on to do something quite different
The same crawler was rewritten for a motorcycle parts wholesaler: instead of news it collected new parts data, filed by year, as the reference source for new materials in their ERP. News and parts specifications have nothing in common, but "go out on a schedule and turn what is there into something the system can use" is exactly the same job.
Outcome
Live since 2021 and still operated by the client.
FAQ
Something similar in mind?
Tell us the thing that is currently costing you the most time. We will tell you whether it is worth building before we talk about how.
Request a quote